Async Web Crawler
A command-line crawler that finds and downloads files from a site concurrently.
- Developer
What it is
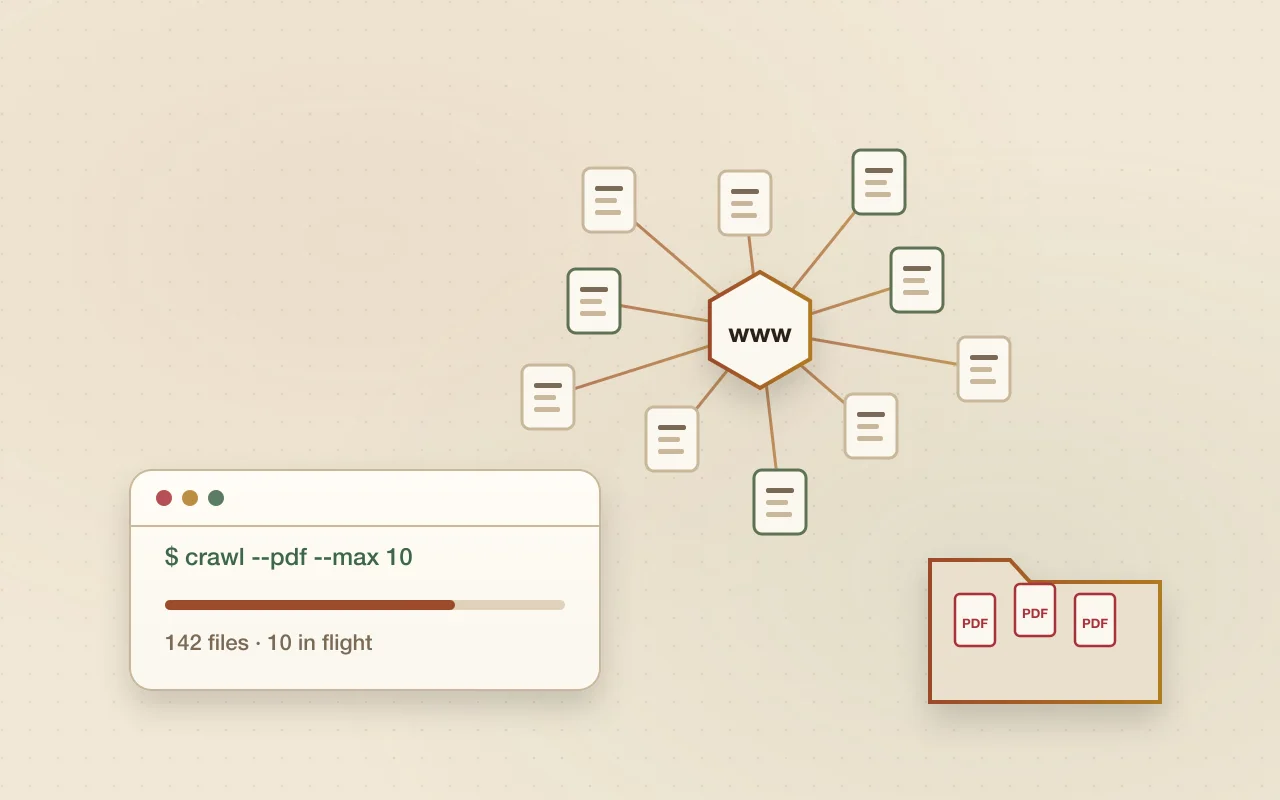
Crawls a website and downloads the files it links to — PDFs by default — using asynchronous requests with a concurrency limit and live progress.
The problem
Downloading hundreds of documents one at a time is slow, and unbounded parallel requests overload the site being crawled.
Architecture
Requests flow left to right. Hover a component for its role.
- Command line client
- aiohttp crawler worker, 10 concurrent requests
- BeautifulSoup parser service
- Downloaded files data
- Progress reporter service, separate thread
Key decisions
Bounded concurrency
A fixed cap on simultaneous requests keeps the crawl fast without hammering the target site.
Highlights
- Asynchronous file writes with aiofiles.
- Progress reported from a separate thread so the crawl never waits on output.